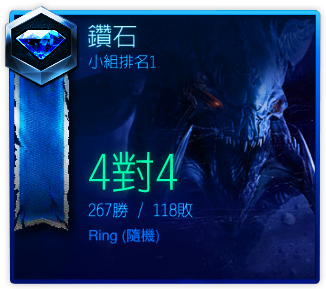
呃…兩個禮拜前才剛達成千勝,今天玩著玩著又將4對4的團戰戰績提升到排名1了...Orz 我果然很喜歡團體作戰方式~ 加上前十名有些都是隊友,打起來格外的刺激~ 接下來呢?應該沒有了... 因為有排些事情來做了。
 blog.Ring.idv.tw
 星海爭霸2 - 4對4鑽石小組排名1
In General, Enjoy Life
呃…兩個禮拜前才剛達成千勝,今天玩著玩著又將4對4的團戰戰績提升到排名1了...Orz 我果然很喜歡團體作戰方式~ 加上前十名有些都是隊友,打起來格外的刺激~ 接下來呢?應該沒有了... 因為有排些事情來做了。
2011-01-20 01:26:04 | Add Comment
MapReduce - Mark/Reset of Values IteratorIn Hadoop
不曉得是否有人和我有同樣的疑問,就是關於能否將reduce function中的「Iterator」改為「ResettableIterator」,雖然這可以在reduce中花額外的功夫來達成,不過總覺得不是一種有效率的方式,最近看了一下Hadoop相關文件,顯然不是只有我有這樣的需求與想法,因為在Hadoop 0.21.0已經將此功能補上了(Values Iterator should support "mark" and "reset"),用法如下:
WordCount - reudce function
public void reduce(Text key, Iterable<IntWritable> values, Context context) throws IOException, InterruptedException
{
	int sum = 0;
	Iterator<IntWritable> i = values.iterator();
	while(i.hasNext())
	{
		sum += i.next().get();
	}
	result.set(sum);
	context.write(key, result);
}
上述程式是一般WordCount程式中的reduce function,假設現在要為「每個單字多累加一次出現次數」,修改後的reduce程式如下:
修改後的WordCount
public void reduce(Text key, Iterable<IntWritable> values, Context context) throws IOException, InterruptedException
{
	int sum = 0;
	MarkableIterator<IntWritable> mitr = new MarkableIterator<IntWritable>(values.iterator());
	mitr.mark();
	while (mitr.hasNext())
	{
		sum += mitr.next().get();
	}
	mitr.reset();
	while (mitr.hasNext())
	{
		sum += mitr.next().get();
	}
	result.set(sum);
	context.write(key, result);
}
從上述程式可以知道它採用「MarkableIterator」來取代先前所使用的「Iterator」,而關於MarkableIterator詳細的實作細節可以從Hadoop 0.21.0 原始碼中的「org.apache.hadoop.mapreduce.task.ReduceContextImpl」程式來查看,另外可以發現原本出現在Hadoop 0.20.x的ValueIterator class(in ReduceContext.java),這在Hadoop 0.21版也都被改寫過了,原先該ValueIterator class只是單純的實作Iteraotr,而這在Hadoop 0.21.0 已將該ValueIterator class改為實作「ReduceContext.ValueIterator」,而ReduceContext.ValueIterator繼承「MarkableIteratorInterface」。
2011-01-19 11:48:54 | Add Comment
星海爭霸2 - 千勝達成In Enjoy Life, General
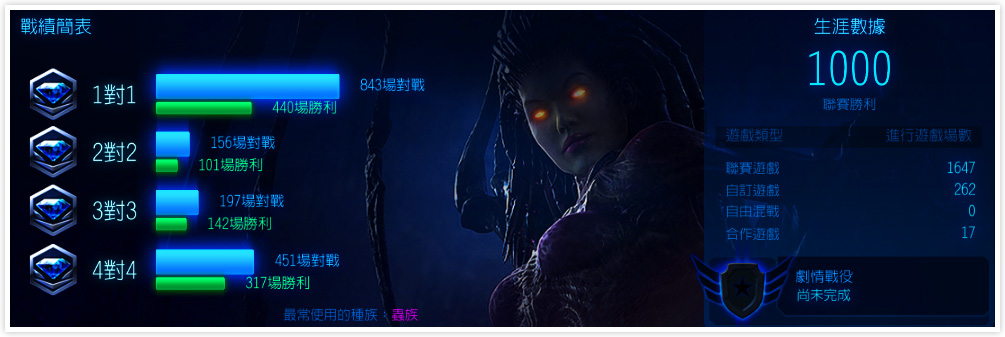
自從約一個多月前達成四鑽等級之後,玩著玩著又在今天給它玩到千勝了... Orz
現在才發現在3對3和4對4的對戰組合中,我的勝率居然有七成以上.... 這... 和我喜歡與人合作的人格特質不曉得有沒有相關?:D
不過似乎又花太多時間在這上面了... 就先到這邊就好~ 接下來要找點別的事來充實充實自己了...
2011-01-06 00:05:28 | Add Comment
Hadoop - Mapper如何處理Split?In Hadoop
在開始進入主題之前,先回顧一下HDFS的儲存方式,在HDFS中預設每個Block Size是64MB(dfs.blocksize:67108864),意指為如果寫一個大於64MB的檔案到HDFS之中,那麼它會自動地將檔案以64MB為基礎來進行切分的動作,這裡我們實驗一個例子:
筆者從「Peter Norvig: How to Write a Spelling Corrector」下載了一個大約包含一佰萬個單詞的純文字文件「big.txt」來實驗,不過由於該檔案約只佔了6MB(6488666),所以透過下述指令將它擴展成大於64MB:
P.S. 請執行12次 = =" (謎之音:有更快的方式嗎?..Orz)
cat big.txt >> test.txt
現在的「test.txt」檔案大約有77MB了(77863992),接著將它寫到HDFS並透過hadoop fsck指令來觀察一下:
bin/hadoop dfs -mkdir /testfile
bin/hadoop dfs -put test.txt /testfile/
bin/hadoop fsck /testfile/test.txt -blocks -files -locations
結果:
0. blk_-4603164807368241811_6252 len=67108864 repl=1 [127.0.0.1:50010]
1. blk_1896285744196882269_6252 len=10755128 repl=1 [127.0.0.1:50010]
從上述的結果來看,「test.txt」的確被切分成兩個Block單位了,分別佔了「67108864」和「10755128」bytes的檔案大小,而從這兩個Block所包含的內容來看可以發現,介於兩個Block之間的「mucous」單詞硬是被拆散成了兩半(「m」和「ucous」)?
blk_-4603164807368241811 - tail
Definition.--Virus.--ACQUIRED SYPHILIS--Primary period:
    _Incubation, primary chancre, glandular enlargement_;
    _Extra-genital chancres_--Treatment--Secondary period: _General
    symptoms, skin affections, m
blk_1896285744196882269 - head
ucous patches, affections of bones,
    joints, eyes_, etc.--Treatment: _Salvarsan_--_Methods of
    administering mercury_--Syphilis and marriage--Intermediate
    stage--_Reminders_--Tertiary period: _General symptoms_,
而這樣的情況在執行MapReduce又是如何處理的?由於在Map階段執行時是一個Mapper對應一個Split,重點就在於該Block最後的「mucous」單字硬是被拆成兩半,而這在Map階段又是如何處理的?總不可能跑個「WordCount」都會有問題吧?而這就是本文的主軸,既然上述「mucous」單詞被拆散成兩半,那麼就應該有對應的處理方式,透過「TextInputFormat」原始碼可以得知它採用「LineRecordReader」來讀取Block的資料內容,如果看過「LineRecordReader」原始碼的話其實已經發現答案了!不過筆者為求實驗正確仍改了一下原始碼去確認,結果證實:
「一個Mapper在讀取一個Block的時候,如果該Block不是檔案(e.g. test.txt)的最後一個Block時,那麼它會多讀取下一個Block的第一行資料」,也就是說處理第一個Block的Mapper最後會讀取「symptoms, skin affections, mucous patches, affections of bones,」這一整行就對了,當然下一個Mapper去處理第二個Block時就自動忽略第一行的資料了,以此類推。
雖然處理的方式很簡單,不過沒看過Source Code就是不曉得它怎麼處理的.. Orz
P.S. 關於這個問題之前同事曾問過我,那時看了Source Code之後一直沒時間實際去驗證它,所以本文記錄了這個驗證過程。
2010-12-07 12:16:18 | Comments (2)
Hadoop - Chaining MapsIn Hadoop
本文主要介紹在Hadoop 0.19.0就開始提供的Chaining Maps(Hadoop-3702)功能,在開始介紹之前先假想下述情況~ 是否曾在一個Mapper中處理許多步驟的事項?或者是否曾在Reducer結束之後還要針對每筆資料個別處理的情況?簡單來說~ 如果在你的MapReduce程式中有需要preprocessing或postprocessing的情況,那就適合用Chaining Maps來完成。
這裡我們假設將MapReduce的執行順序用「[MR]+」符號來表示,那麼透過Chaining Maps所執行的工作就可以用「M+RM*」來表示,代表可以執行一個以上的Mapper(preprocessing),接著在Reducer之後再由零或多個Mapper做後續的處理(postprocessing),這樣的作法可以帶來一些額外的好處,譬如:方便除錯、測試、易維護以及MapReduce程式的可重用性,下述是一個簡單的展示範例,主要藉由「ChainMapper」和「ChainReducer」兩個類別來完成,此範例執行的順序為:「WordSegmentationMap | StopWordMap | Reduce | FilterMap」。
Chaining Maps for Hadoop 0.21.x
import java.io.IOException;
import java.util.HashSet;
import java.util.Set;

import org.apache.hadoop.conf.Configuration;
import org.apache.hadoop.fs.FileSystem;
import org.apache.hadoop.fs.Path;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.LongWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Cluster;
import org.apache.hadoop.mapreduce.Job;
import org.apache.hadoop.mapreduce.Mapper;
import org.apache.hadoop.mapreduce.Reducer;
import org.apache.hadoop.mapreduce.lib.chain.ChainMapper;
import org.apache.hadoop.mapreduce.lib.chain.ChainReducer;
import org.apache.hadoop.mapreduce.lib.input.TextInputFormat;
import org.apache.hadoop.mapreduce.lib.output.TextOutputFormat;


public class ChainExample
{
	public static class WordSegmentationMap extends Mapper<LongWritable, Text, Text, IntWritable>
	{
		@Override
		public void map(LongWritable key, Text value , Context context) throws IOException, InterruptedException
		{
			String s[] = value.toString().split(" ");
			for(String w : s)
				context.write(new Text(w), new IntWritable(1));

		}
	}
	public static class StopWordMap extends Mapper<Text, IntWritable, Text, IntWritable>
	{
		private Set<String> stopwords = new HashSet<String>();
		public static final String[] ENGLISH_STOP_WORDS = {
		    "a", "and", "are", "as", "at", "be", "but", "by",
		    "for", "if", "in", "into", "is", "it",
		    "no", "not", "of", "on", "or", "s", "such",
		    "t", "that", "the", "their", "then", "there", "these",
		    "they", "this", "to", "was", "will", "with"
		  };

		protected void setup(Context context) throws IOException, InterruptedException
		{
			for(int i = 0 ; i < ENGLISH_STOP_WORDS.length ; i++)
				stopwords.add(ENGLISH_STOP_WORDS[i]);
		}
		@Override
		public void map(Text key, IntWritable value , Context context) throws IOException, InterruptedException
		{
			if(!stopwords.contains(key.toString()))
				context.write(key, value);
		}
	}

	public static class Reduce extends Reducer<Text, IntWritable, Text, IntWritable>
	{
		@Override
		public void reduce(Text key, Iterable<IntWritable> values, Context context) throws IOException, InterruptedException
		{
			int sum = 0;
			for(IntWritable i : values)
				sum++;

			context.write(key, new IntWritable(sum));
		}
	}
	public static class FilterMap extends Mapper<Text, IntWritable, IntWritable,Text>
	{
		@Override
		public void map(Text key, IntWritable value, Context context) throws IOException, InterruptedException
		{
			if(value.get()>100)
				context.write(value, key);
		}
	}

	public static void main(String[] args)throws Exception
	{
		String output = "/chainExample_out/";
		Configuration conf = new Configuration();
		Cluster cluster = new Cluster(conf);

		FileSystem fs = FileSystem.get(conf);
		fs.delete(new Path(output), true);

		Job job = Job.getInstance(cluster);
		job.setJarByClass(ChainExample.class);
		job.setJobName("ChainExample");
		job.setInputFormatClass(TextInputFormat.class);
		job.setOutputFormatClass(TextOutputFormat.class);
		TextInputFormat.setInputPaths(job, new Path("/chainExample/*"));
		TextOutputFormat.setOutputPath(job, new Path(output));

		ChainMapper.addMapper(job, WordSegmentationMap.class, LongWritable.class, Text.class, Text.class, IntWritable.class,  new Configuration(false));
		ChainMapper.addMapper(job, StopWordMap.class, Text.class, IntWritable.class, Text.class, IntWritable.class,  new Configuration(false));
		ChainReducer.setReducer(job, Reduce.class, Text.class, IntWritable.class, Text.class, IntWritable.class, new Configuration(false));
		ChainReducer.addMapper(job, FilterMap.class, Text.class, IntWritable.class, IntWritable.class, Text.class, new Configuration(false));
		job.waitForCompletion(true);
	}
}
2010-12-01 10:17:15 | Comments (13)