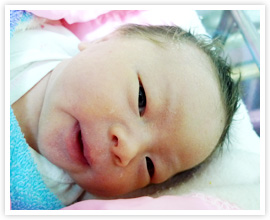
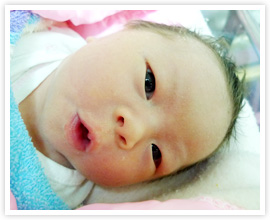
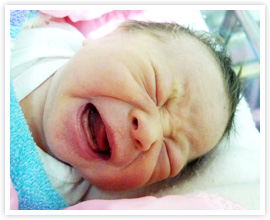
上面的三連拍就是我那親愛的姪女~ 2月20日剛降臨在這個世界上~ 她未來應該是一位活潑+外向的女生 ^^ 而我也就因此多了個「舅舅」的身份~
剛見到時覺得怎麼那麼小一隻~ 哈哈~ 只有可愛兩個字可以形容吧~
回到新竹就要面臨許多事項的處理~ 這陣子努力不夠...嗯~ 繼續加油了! 必須讓自己保持在從正面的角度來處事。
 blog.Ring.idv.tw
 多了個新的身份...
In Enjoy Life
上面的三連拍就是我那親愛的姪女~ 2月20日剛降臨在這個世界上~ 她未來應該是一位活潑+外向的女生 ^^ 而我也就因此多了個「舅舅」的身份~
剛見到時覺得怎麼那麼小一隻~ 哈哈~ 只有可愛兩個字可以形容吧~
回到新竹就要面臨許多事項的處理~ 這陣子努力不夠...嗯~ 繼續加油了! 必須讓自己保持在從正面的角度來處事。
2009-02-23 00:52:33 | Comments (4)
Average Length of URL?In Hadoop
從過年前到目前為止~ 都一直和學弟忙於將以前所實作的東西要轉換到線上版,我還需要點時間呀~ ><"
而在轉換的過程之中~ 突然想到一個問題!! 那就是全世界URL的平均長度究竟約多長?
我想這個答案只有大型搜尋引擎(Google、Yahoo、Cuil)能給出一個較接近的答案吧~
下述是一個簡單計算這樣結果的MapReduce小程式:
URLList
http://l.yimg.com/f/a/tw/ivychang/708971_020409_420x80_0202_yahoo-elite.swf
http://l.yimg.com/tw.yimg.com/a/tw/ivychang/712756_1231_1231new350_100.swf
http://l.yimg.com/tw.yimg.com/a/tw/erinlin/721493_0123_350x200.swf
http://www.kriesi.at/wp-content/themes/dark_rainbow/js/Particles.swf
http://tw.promo.yahoo.com/2008auction/shpticket/images/top.swf
http://l.yimg.com/tw.yimg.com/a/tw/fanny/658216_101508_420x80_4.swf
http://l.yimg.com/f/a/tw/vikii/606895_shopping_center_20090203r.swf
http://l.yimg.com/f/a/tw/hedy/697827_e3_hp_012109.swf
http://l.yimg.com/tw.yimg.com/a/tw/ivychang/708334_0120_350x200_certificate_081224.swf
http://l.yimg.com/tw.yimg.com/a/tw/ivychang/708334_0120_350x100_linux_080826.swf
http://www.ysed.org.tw/3rd_upLoad/4156/index.swf
URLAvgLength
import java.io.BufferedReader;
import java.io.IOException;
import java.io.InputStream;
import java.io.InputStreamReader;
import java.util.Iterator;
import org.apache.hadoop.conf.Configuration;
import org.apache.hadoop.conf.Configured;
import org.apache.hadoop.fs.FileSystem;
import org.apache.hadoop.fs.Path;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.LongWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapred.Counters;
import org.apache.hadoop.mapred.JobClient;
import org.apache.hadoop.mapred.JobConf;
import org.apache.hadoop.mapred.MapReduceBase;
import org.apache.hadoop.mapred.Mapper;
import org.apache.hadoop.mapred.OutputCollector;
import org.apache.hadoop.mapred.Reducer;
import org.apache.hadoop.mapred.Reporter;
import org.apache.hadoop.mapred.RunningJob;
import org.apache.hadoop.mapred.TextInputFormat;
import org.apache.hadoop.mapred.TextOutputFormat;
import org.apache.hadoop.util.Tool;
import org.apache.hadoop.util.ToolRunner;

public class URLAvgLength extends Configured implements Tool {

	static enum Counter {
		URL_COUNT
	}

	public static class Map extends MapReduceBase implements
			Mapper<LongWritable, Text, Text, IntWritable> {

		private final static Text word = new Text("Len");

		public void map(LongWritable key, Text value,
				OutputCollector<Text, IntWritable> output, Reporter reporter)
				throws IOException {

			String key2 = value.toString();
			reporter.incrCounter(Counter.URL_COUNT, 1);
			output.collect(word, new IntWritable(key2.length()));
		}
	}

	public static class Reduce extends MapReduceBase implements
			Reducer<Text, IntWritable, Text, IntWritable> {

		public void reduce(Text key, Iterator<IntWritable> values,
				OutputCollector<Text, IntWritable> output, Reporter reporter)
				throws IOException {

			int sum = 0;
			while (values.hasNext()) {
				sum += values.next().get();
			}

			output.collect(key, new IntWritable(sum));
		}
	}

	public int run(String[] args) throws Exception {
		String input = "/usr/Ring/urllist/*";
		String output = "/usr/Ring/urlavglen";
		JobConf conf = new JobConf(getConf(), URLAvgLength.class);
		FileSystem fs = FileSystem.get(conf);
		fs.delete(new Path(output), true);

		conf.setJobName("URLAvgLength");
		conf.setOutputKeyClass(Text.class);
		conf.setOutputValueClass(IntWritable.class);

		conf.setMapperClass(Map.class);
		conf.setCombinerClass(Reduce.class);
		conf.setReducerClass(Reduce.class);

		conf.setInputFormat(TextInputFormat.class);
		conf.setOutputFormat(TextOutputFormat.class);

		conf.setNumReduceTasks(1);

		TextInputFormat.setInputPaths(conf, new Path(input));
		TextOutputFormat.setOutputPath(conf, new Path(output));

		RunningJob running = JobClient.runJob(conf);
		Counters ct = running.getCounters();
		long count = ct.getCounter(Counter.URL_COUNT);

		InputStream in = fs.open(new Path("hdfs://localhost:9000"+output+"/part-00000"));
		BufferedReader br = new BufferedReader(new InputStreamReader(in));
		String line = br.readLine();
		Integer value = Integer.parseInt(line.split("\t")[1]);
		System.out.println("Avg:" + value/count);
		return 0;
	}

	public static void main(String[] args) {
		try {
			int res = ToolRunner.run(new Configuration(), new URLAvgLength(),args);
			System.exit(res);
		} catch (Exception e) {
			e.printStackTrace();
		}

	}
}
Avg:67
2009-02-07 02:29:48 | Comments (1)
Memcached - a distributed memory object caching systemIn Open Source
Memcached(pronunciation: mem-cache-dee.)是一套分散式的記憶體快取系統~ 這年頭實在是什麼都要分散式的~XD
尤其從Google的身上更是如此~Google File System、MapReduce、Bigtable... 全部都是分散式的..= ="(因為後兩者均架構在GFS之上)
根據memcached(wiki)上的解說~ 它原本是由「Danga Interactive」公司所為了開發「LiveJournal」而誕生的~ 它可以用在大部份database-driven的網站下~ (本部落格應該也要改用Memcached吧~ XD 有時間再說~),也就是說~ 我們可以快取一些經常要從資料庫抓出來的資料~ 然而它並沒有提供任何安全性或是認證的功能~ 換句話說~ Memcached需要被安置在防火牆的保護之下~ 而且許多大咖級的公司都有在用~ 像是YouTube、Digg、Wikipedia、Slashdot... Facebook更是用了超過800臺伺服器,並提供「28TB」級的記憶體來作為快取使用~ (心想Google應該更多..),重點~ 在UMD的一位Jimmy Lin助理教授~ 很快的就將它整合到Hadoop之中~ 還寫了份技術報告「Low-Latency, High-Throughput Access to Static Global Resources within the Hadoop Framework.」.. 真是先驅..Orz
關於安裝Memcached網路上已經有許多資源了~ 有興趣的人Google一下就行了~ 或參考下述相關資源。
筆者主要用「spymemcached」這一個Java API,如果您需要其它語言的API請參考:Memcached Clients。
下述是印出相關Memcached Server的狀態程式:
import java.net.SocketAddress;
import java.util.Map;

import net.spy.memcached.AddrUtil;
import net.spy.memcached.MemcachedClient;

public class MemcachedTest
{
	public static void main(String arg[]) throws Exception
	{
		long total_items = 0;
		MemcachedClient mc = new MemcachedClient(AddrUtil.getAddresses("xxx.xxx.xxx.xxx:11211"));

		Map<SocketAddress, Map<String, String>> stats = mc.getStats();

		for (Map.Entry<SocketAddress, Map<String, String>> e : stats.entrySet())
		{
			System.out.println("memcached server: " + e.getKey().toString());

			for (Map.Entry<String, String> s : e.getValue().entrySet())
			{
				System.out.println(" - " + s.getKey() + ": " + s.getValue());

				if (s.getKey().equals("curr_items"))
					total_items += Long.parseLong(s.getValue());

			}
		}

		System.out.println("Total number items in memcache: " + total_items);
		mc.shutdown();
	}
}
相關消息與資源
2009-01-13 22:31:18 | Comments (2)
Java class File FormatIn Java
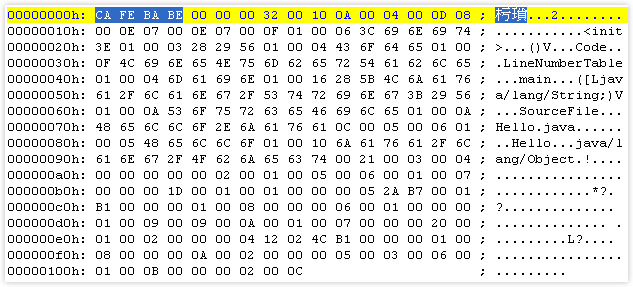
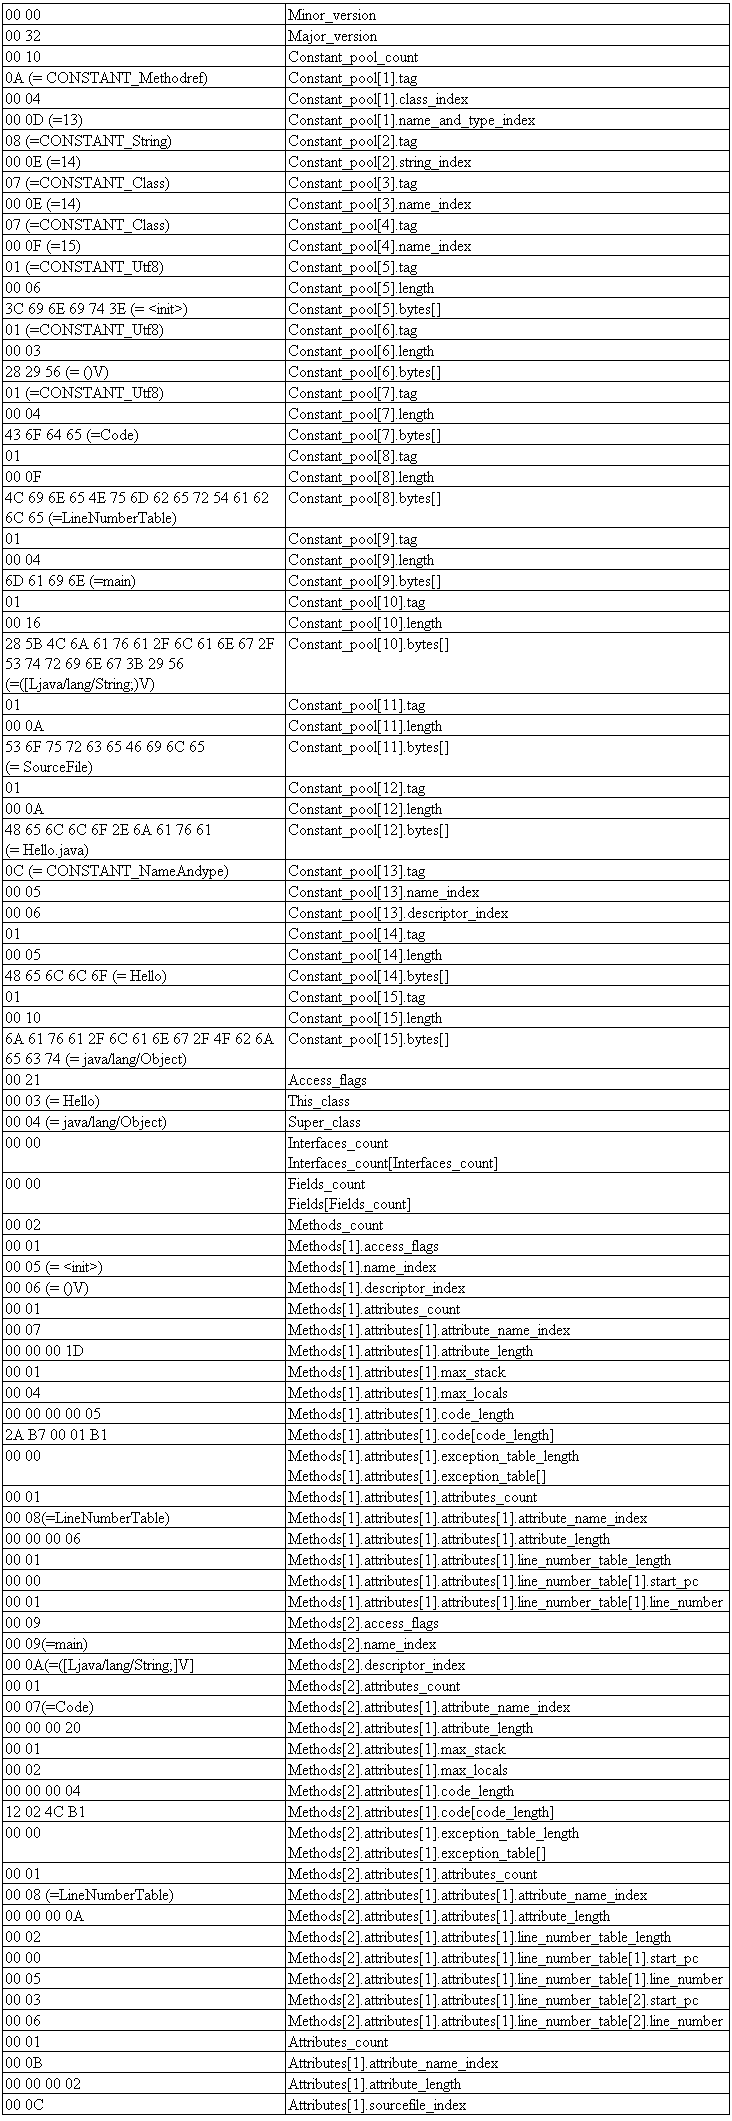
昨天試著在整理電腦的東西~ 發現一個塵封已久的Word檔~ 裡頭包含的是以前研究Java class File Format記錄~
還記得當初剛看到「0xCAFEBABE」真是會心一笑啊~ 咖啡寶寶?XDDD 是的,沒錯! Java就是拿這四個Bytes當做File Signature,真是有創意極了!!
依稀記得這個class format曾經大幅更動過一次~ 那時候是從「Java 1.4.x」直接跳到「Java 5.0」,而當時最流行的就是「二隻老虎」~ 一隻是Java 5.0的代號「Tiger」,另一隻則是「Mac OS X 10.4」代號也稱為「Tiger」~ 直到去年才被「自然界」所取代... 因為開始出現很多的「Cloud」和「Air」.. 不是「雲」就是「大氣」~ 不勝枚舉 XDD(Cloud Computing、Tag Cloud、Adobe AIR、MacBook AIR...)
上述格式的原始檔如下:
Hello.java
public class Hello
{
	public static void main(String arg[])
	{
		String s = "Hello";
	}
}
有興趣的人可以對照著「VM Spec The class File Format」來剖析~
而Java 5.0 更動的class format請至「JSR 202: JavaTM Class File Specification Update」下載。
筆者的記錄檔:Hello.class 格式剖析 (整張圖放上來會漏漏長...)
2009-01-06 12:54:34 | Add Comment
Pairwise Document Similarity in Large Collections with MapReduceIn Hadoop
Pairwise Document Similarity in Large Collections with MapReduce.這是一篇由UMD的一位博士生Tamer M. Elsayed和他的指導教授所共同發表在「ACL-08: HLT」的短篇論文,主要用「MapReduce」來處理大量文件相似度的計算,如果您對這篇論文有興趣的話,請參考上述論文連結,筆者不再詳述。
下述筆者撰寫的驗證程式需要用到「Cloud9 - A MapReduce Library for Hadoop」,「Cloud9」是由UMD所開發的,主要用來作為課程的教學工具和一些文字處理方面的研究,它採用Apache License,所以您可以直接用Subversion checkout下來使用,而下述範例主要用到「PairOfIntString」和「ArrayListWritable」。
Pairwise Document Similarity
在進行「Pairwise Similarity」的「Map」階段時,筆者純粹利用Regular Expression來處理~ 這並不是最佳的處理方式(我承認偷懶~),最佳的方式應該撰寫一些特定的「OutputFormat」和「Writable」來加以處理,整個效率才會大大的提高!(如:Cloud9所提供的Tuple)
由於此範例需要處理二次的MapReduce,所以筆者直接利用「job2.addDependingJob(job1);」將兩個Job產生相依性,也就是先執行job1完成之後JobControl才會去呼叫job2開始執行。
import java.io.IOException;
import java.util.*;
import java.util.regex.Matcher;
import java.util.regex.Pattern;
import org.apache.hadoop.conf.Configuration;
import org.apache.hadoop.conf.Configured;
import org.apache.hadoop.fs.Path;
import org.apache.hadoop.io.*;
import org.apache.hadoop.mapred.*;
import org.apache.hadoop.mapred.jobcontrol.Job;
import org.apache.hadoop.mapred.jobcontrol.JobControl;
import org.apache.hadoop.util.Tool;
import org.apache.hadoop.util.ToolRunner;

import edu.umd.cloud9.io.ArrayListWritable;
import edu.umd.cloud9.io.PairOfIntString;

public class PairwiseDS extends Configured implements Tool
{

    public static class Map extends MapReduceBase implements
            Mapper<LongWritable, Text, Text, PairOfIntString>
    {
        private Text word = new Text();

        public void map(LongWritable key, Text value,
                OutputCollector<Text, PairOfIntString> output, Reporter reporter)
                throws IOException
        {
            FileSplit fileSplit = (FileSplit) reporter.getInputSplit();
            String fileName = fileSplit.getPath().getName();
            fileName = fileName.substring(0, fileName.length() - 4);

            String line = value.toString();
            StringTokenizer tokenizer = new StringTokenizer(line);
            while (tokenizer.hasMoreTokens())
            {
                word.set(tokenizer.nextToken());
                output.collect(word, new PairOfIntString(1, fileName));
            }
        }
    }

    public static class Reduce extends MapReduceBase implements
            Reducer<Text, PairOfIntString, Text, ArrayListWritable>
    {
        public void reduce(Text key, Iterator<PairOfIntString> values,
                OutputCollector<Text, ArrayListWritable> output,
                Reporter reporter) throws IOException
        {

            ArrayList<PairOfIntString> al = new ArrayList<PairOfIntString>();
            HashMap<String, Integer> map = new HashMap<String, Integer>();

            while (values.hasNext())
            {
                PairOfIntString psi = values.next();
                if (map.containsKey(psi.getRightElement()))
                {
                    Integer i = (Integer) map.get(psi.getRightElement());
                    map.put(psi.getRightElement(), i.intValue() + 1);
                } else
                {
                    map.put(psi.getRightElement(), psi.getLeftElement());
                }
            }
            Iterator i = map.entrySet().iterator();
            while (i.hasNext())
            {
                java.util.Map.Entry m = (java.util.Map.Entry) i.next();
                al.add(new PairOfIntString((Integer) m.getValue(), (String) m
                        .getKey()));
            }
            output.collect(key, new ArrayListWritable<PairOfIntString>(al));

        }
    }

    public static class Map2 extends MapReduceBase implements
            Mapper<LongWritable, Text, Text, IntWritable>
    {
        private Text word = new Text();

        public void map(LongWritable key, Text value,
                OutputCollector<Text, IntWritable> output, Reporter reporter)
                throws IOException
        {
            String line = value.toString().trim();

            ArrayList<String> keyList = new ArrayList<String>();
            ArrayList<Integer> valList = new ArrayList<Integer>();

            String p = "\\(([0-9]+), ([a-z0-9.]+)\\)";
            Pattern r = Pattern.compile(p);
            Matcher m = r.matcher(line);
            while (m.find())
            {
                String k = m.group(2);
                String v = m.group(1);
                keyList.add(k);
                valList.add(new Integer(v));
            }

            if (keyList.size() > 1)
            {
                String[] key_arr = keyList.toArray(new String[0]);
                Integer[] val_arr = valList.toArray(new Integer[0]);
                int klen = key_arr.length;
                for (int i = 0; i < klen; i++)
                {
                    for (int j = i + 1; j < klen; j++)
                    {
                        word.set(key_arr[i] + "," + key_arr[j]);
                        output.collect(word, new IntWritable(val_arr[i]
                                * val_arr[j]));
                    }
                }
            }

        }
    }

    public static class Reduce2 extends MapReduceBase implements
            Reducer<Text, IntWritable, Text, IntWritable>
    {
        public void reduce(Text key, Iterator<IntWritable> values,
                OutputCollector<Text, IntWritable> output, Reporter reporter)
                throws IOException
        {
            int sum = 0;
            while (values.hasNext())
            {
                sum += values.next().get();
            }
            output.collect(key, new IntWritable(sum));
        }
    }

    public int run(String[] args) throws Exception
    {
        // ===================== Indexing =====================
        JobConf conf = new JobConf(getConf(), PairwiseDS.class);
        conf.setJobName("Indexing");
        conf.setOutputKeyClass(Text.class);
        conf.setOutputValueClass(PairOfIntString.class);

        conf.setMapperClass(Map.class);
        conf.setReducerClass(Reduce.class);

        conf.setInputFormat(TextInputFormat.class);
        conf.setOutputFormat(TextOutputFormat.class);

        conf.setNumReduceTasks(1);
        FileInputFormat.setInputPaths(conf, new Path(args[0]));
        TextOutputFormat.setOutputPath(conf, new Path(args[1]));

        Job job1 = new Job(conf);
        // ===================== Pairwise Similarity =====================
        JobConf conf2 = new JobConf(getConf(), PairwiseDS.class);
        conf2.setJobName("Pairwise Similarity");
        conf2.setOutputKeyClass(Text.class);
        conf2.setOutputValueClass(IntWritable.class);

        conf2.setMapperClass(Map2.class);
        conf2.setReducerClass(Reduce2.class);

        conf2.setInputFormat(TextInputFormat.class);
        conf2.setOutputFormat(TextOutputFormat.class);
        conf2.setNumReduceTasks(1);

        FileInputFormat.setInputPaths(conf2, new Path(args[1] + "/p*"));
        TextOutputFormat.setOutputPath(conf2, new Path(args[2]));
        Job job2 = new Job(conf2);

        job2.addDependingJob(job1);
        JobControl controller = new JobControl("Pairwise Document Similarity");
        controller.addJob(job1);
        controller.addJob(job2);
        new Thread(controller).start();

        while (!controller.allFinished())
        {
            System.out.println("Jobs in waiting state: "+ controller.getWaitingJobs().size());
            System.out.println("Jobs in ready state: "+ controller.getReadyJobs().size());
            System.out.println("Jobs in running state: "+ controller.getRunningJobs().size());
            System.out.println("Jobs in success state: "+ controller.getSuccessfulJobs().size());
            System.out.println("Jobs in failed state: "+ controller.getFailedJobs().size());
            System.out.println();

            try
            {
                Thread.sleep(20000);
            } catch (Exception e)
            {
                e.printStackTrace();
            }
        }
        return 0;

    }

    public static void main(String[] args) throws Exception
    {
        int res = ToolRunner.run(new Configuration(), new PairwiseDS(), args);
        System.exit(res);
    }
}
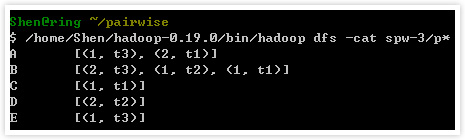
after Indexing:
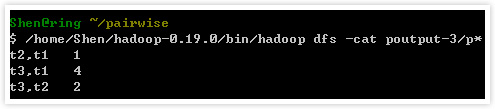
after Pairwise Similarity:
相關資源
2009-01-05 22:30:04 | Comments (4)